RADAR: Catch gray failures with anomaly detection
How real-time anomaly detection catches silent, partial outages in minutes — and how to build the same system on Databricks.
- Gray failures slip past green dashboards, quietly costing you customers and revenue before anyone notices.
- RADAR is a four-stage, metric-agnostic pattern — reliability metrics, anomaly detection, alerting, and root-cause analysis — that Databricks runs on itself to catch these failures in minutes, at over 90% precision and 95% faster discovery.
- You can build the same system on Databricks for any metric — billing, conversion, or model performance — using native components and an AI-agent scaffold.
Some of the most damaging outages are the ones your monitoring never flags: a slice of your customers quietly fails while every health check still reads normal. These "gray failures" leak users and revenue for hours before anyone connects the dots. This post is about catching them early with anomaly detection — how we do it at Databricks with a system called RADAR, and how you can build the same thing for whatever metric matters most to your business. It's written for the people who own service reliability: SREs, platform and data engineers, on-call responders, and the engineering leaders they answer to.
When everything is green but nothing is fine
Picture a normal Wednesday. Keeping a customer-facing service reliable is your job, and every dashboard on your wall is green — CPU healthy, latency fine, servers up, database connected. By every signal your team watches, the system looks perfect.
It isn’t.
- 9:30 — A routine deploy slips a subtle bug into your checkout flow.
- 9:35 — One in twenty customers paying by credit card silently fails. After a couple of retries, they give up and leave.
- 12:40 — The first support ticket lands. It looks like just another mistyped card number, so nobody blinks.
- 14:20 — Two more tickets arrive on the same issue.
- 14:25 — Your support lead spots the pattern and escalates.
- 16:00 — Engineers track down the bug and ship a fix.
For nearly seven hours, your monitoring insisted everything was fine while customers walked and revenue leaked.
What is a gray failure?
That Wednesday is a textbook gray failure. On the surface everything looks healthy; underneath, one specific piece has quietly stopped working — and it hurts customers without ever tripping an alert.
Two things make gray failures so sneaky:
- They’re partial. It’s not everyone — just one slice, like a single type of credit card. There’s no server crash you’d catch instantly, just a messy middle where most users are fine and one group fails the whole time.
- They grow. What starts as a handful of affected customers spreads. Left alone, more and more people hit the same wall.
Think of it as smoke behind the wall. From the outside the house looks fine, but inside the damage is spreading — and the longer you wait, the bigger the blast radius. Researchers have a name for the underlying problem, too: Microsoft’s Gray Failure: The Achilles’ Heel of Cloud-Scale Systems calls it differential observability — your failure detectors don’t notice a problem even while your users clearly do.
Why waiting for customer reports fails
Most teams handle gray failures exactly the way that Wednesday played out: they wait for customers to tell them. Customer reports matter — they’re real human pain — but your customers shouldn’t be your monitoring system. Leaning on reports alone has three problems:
- It’s manual. Someone has to notice the same complaint across a pile of tickets. That’s easy to miss.
- It’s delayed. By the time enough people complain for anyone to connect the dots, hours or days have passed.
- It’s silent. Most affected customers never file a ticket at all. They just leave.
The fix isn’t to stop reading tickets — keep doing that. It’s to add automatic detection that runs all the time and catches what people miss. Concretely, you want something that fires the moment a lot more customers than usual start hitting the same issue at the same time.
| Customer reports alone | Add automatic detection |
|---|---|
| Manual — easy to miss | Catches what people miss |
| Delayed — noticed in days | Fast — noticed in real time |
| Customers suffer in silence | Flags the spike — many users at once |
Meet RADAR
That’s the idea behind RADAR — Reliability Anomaly Detection, Alerting, and Root-cause analysis. We built it at Databricks to catch gray failures in minutes instead of hours. The name fits: when visibility is low, you don’t wait until something hits you — you scan for weak signals early.
Here’s how we point it at one especially useful signal: user errors.
A gray failure often shows up as a sudden spike in errors that look like the user’s fault. Picture a bunch of users in one region who suddenly can’t spin up a certain type of cluster. Each request fails with INVALID_ARGUMENT - an error that is politely saying, “this one’s on you.”
But when many users hit the same “your fault” error at the same moment, it stops being their fault. It’s ours. That spike is exactly the pattern RADAR is built to catch.
The four stages of RADAR
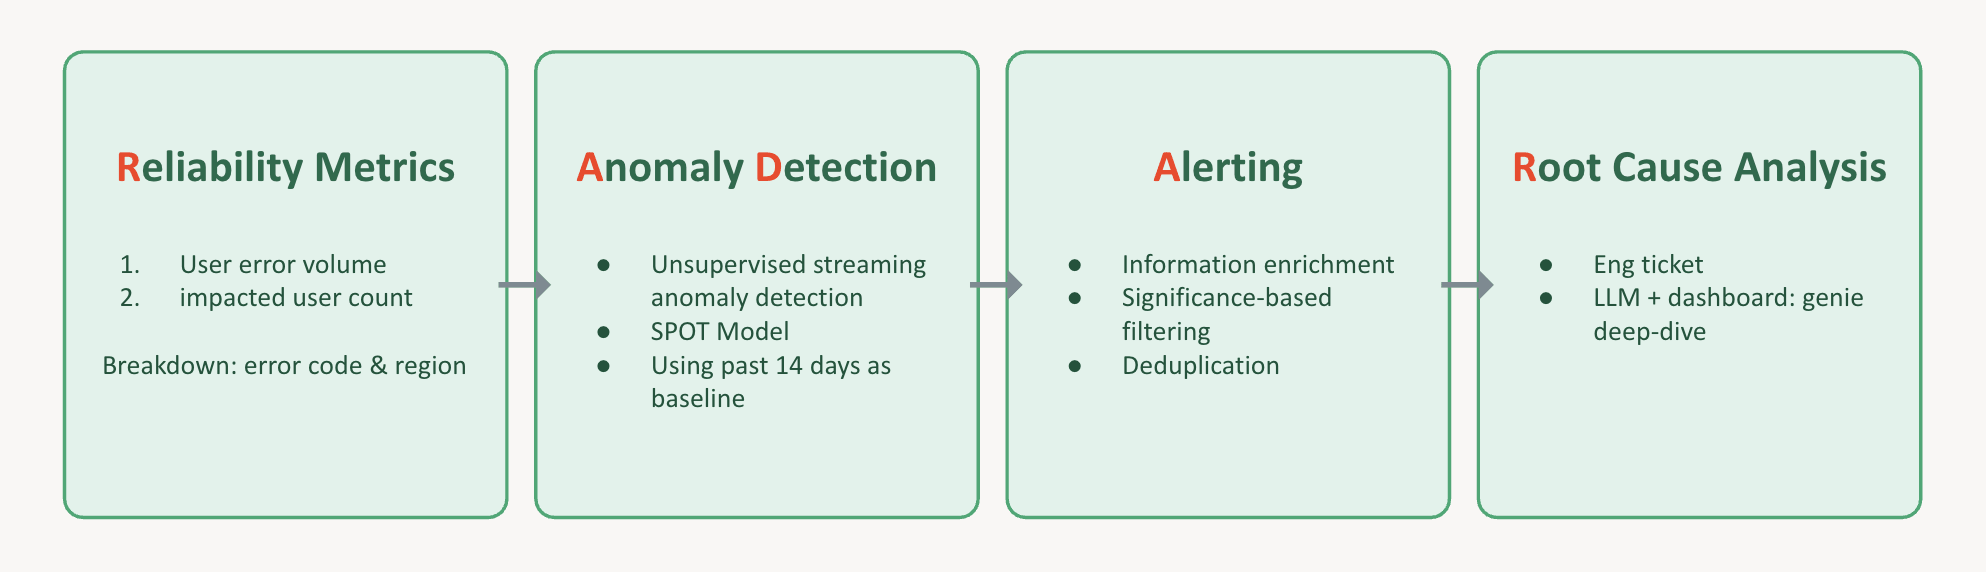
RADAR turns that instinct into a pipeline with four stages:
- Reliability metrics. At every point in time, record two things: how many errors are happening, and how many separate users hit each one. Break it down by error code and region. Now you have a rich set of time series describing the health of your service.
- Anomaly detection. Run anomaly detection on each of those series so the system flags anything that looks off — without you hand-tuning a pile of thresholds. We use an unsupervised, streaming model called SPOT, which learns what “normal” looks like from the past 14 days and needs only a single risk parameter instead of manual cutoffs. (SPOT comes from Siffer et al.’s Anomaly Detection in Streams with Extreme Value Theory, KDD 2017.)
- Alerting. When something fires, the alerting layer takes over. It enriches the alert with context, filters out what isn’t significant, and dedupes so on-call isn’t buried under copies of the same thing. Then it files a ticket routed to the right engineering team for that error.
- Root-cause analysis. Every ticket arrives with anomaly deep-dive details and a link to a dashboard backed by an AI assistant, AI/BI Genie. Whoever’s on call can go straight to figuring out what actually broke, in the least time possible.
What we achieved
Running RADAR on ourselves changed the shape of these incidents. Before, we waited on customer tickets to discover such incidents, leading to days of delay. With RADAR, we achieved a 95% reduction in incident-discovery time, at over 90% precision, with no human needed to spot the pattern. As a result, we are able to keep the blast radius of gray failures contained.
Point RADAR at any metric
Here’s the part that matters most for you: RADAR doesn’t care what the metric is. We happen to point it at user errors, but the same pattern works anywhere a number can quietly go wrong:
- Financial services — payment and transaction failures, billing anomalies, fraud signals
- Retail and e-commerce — checkout conversion, cart errors, delivery times
- Healthcare and life sciences — patient throughput, claims processing
- Any AI product — model performance and data-distribution drift that shows up before a model visibly breaks
It’s the same pattern under different settings. Anywhere you have something that could quietly go wrong, RADAR applies.
Build it yourself on Databricks
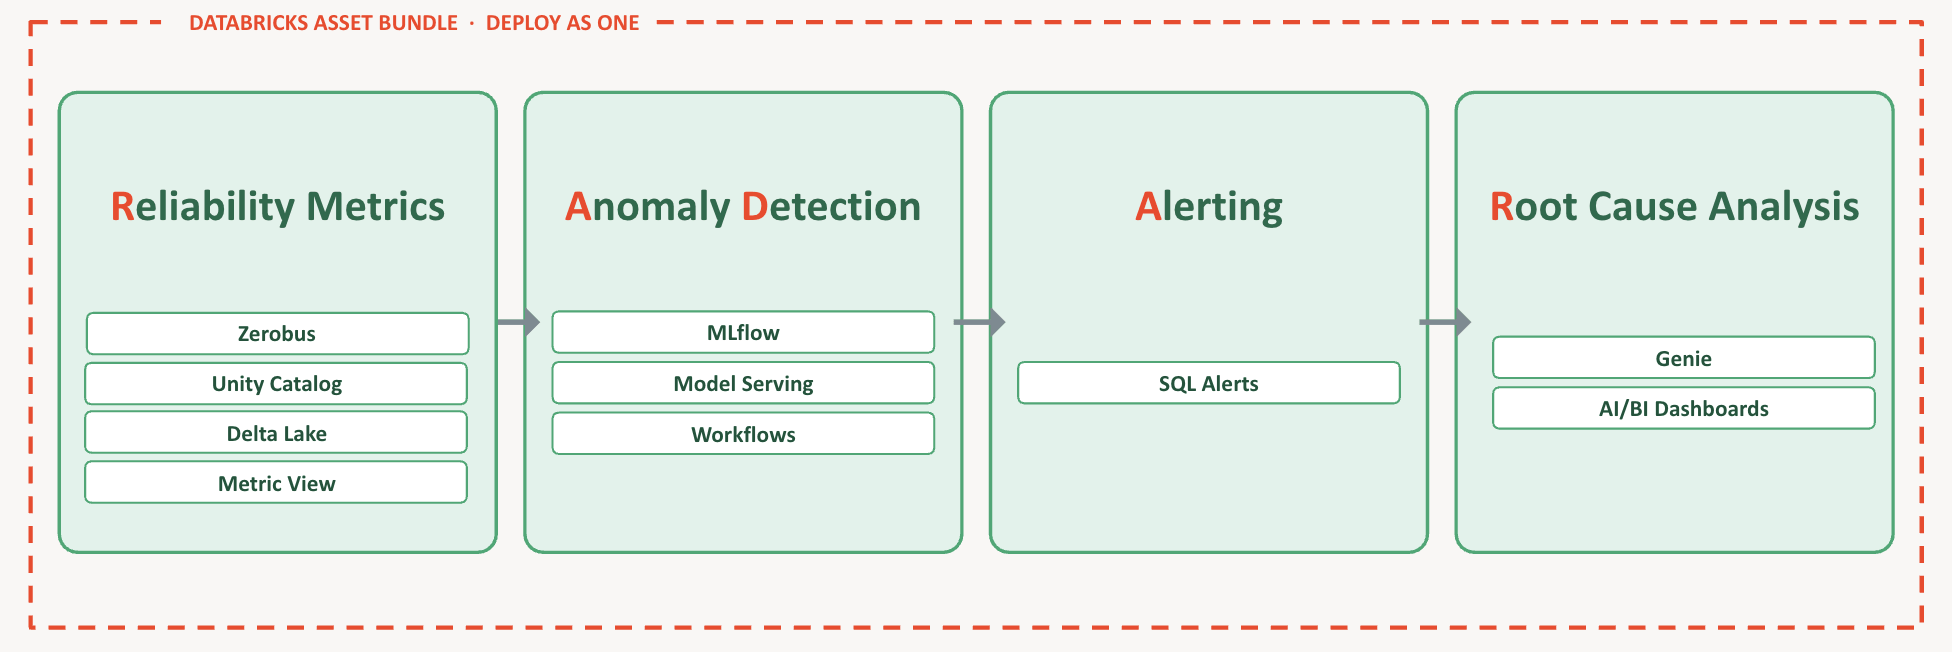
The best news: every piece you need is already on Databricks. Map the four stages to the platform and it looks like this:
- Reliability metrics — Zerobus for low-latency ingest, Unity Catalog and Metric View for governance, Delta Lake for storage
- Anomaly detection — MLflow for model training, Model Serving to deliver the model endpoint, and Workflows to orchestrate the recurrent jobs
- Alerting — Databricks SQL Alerts to fire alerts
- Root-cause analysis — AI/BI Genie and AI/BI Dashboards
And the whole thing deploys as a single unit through a Declarative Asset Bundle (DAB).
Wiring all those parts together by hand is the annoying bit — so we removed it. We distilled the entire internal RADAR system into a single scaffold: one markdown file that works like a recipe, mapping each part of RADAR to a specific Databricks component (collect and store → a Delta table; detect the anomaly → a job; alert and dedupe → a ticket; visualize → a dashboard).
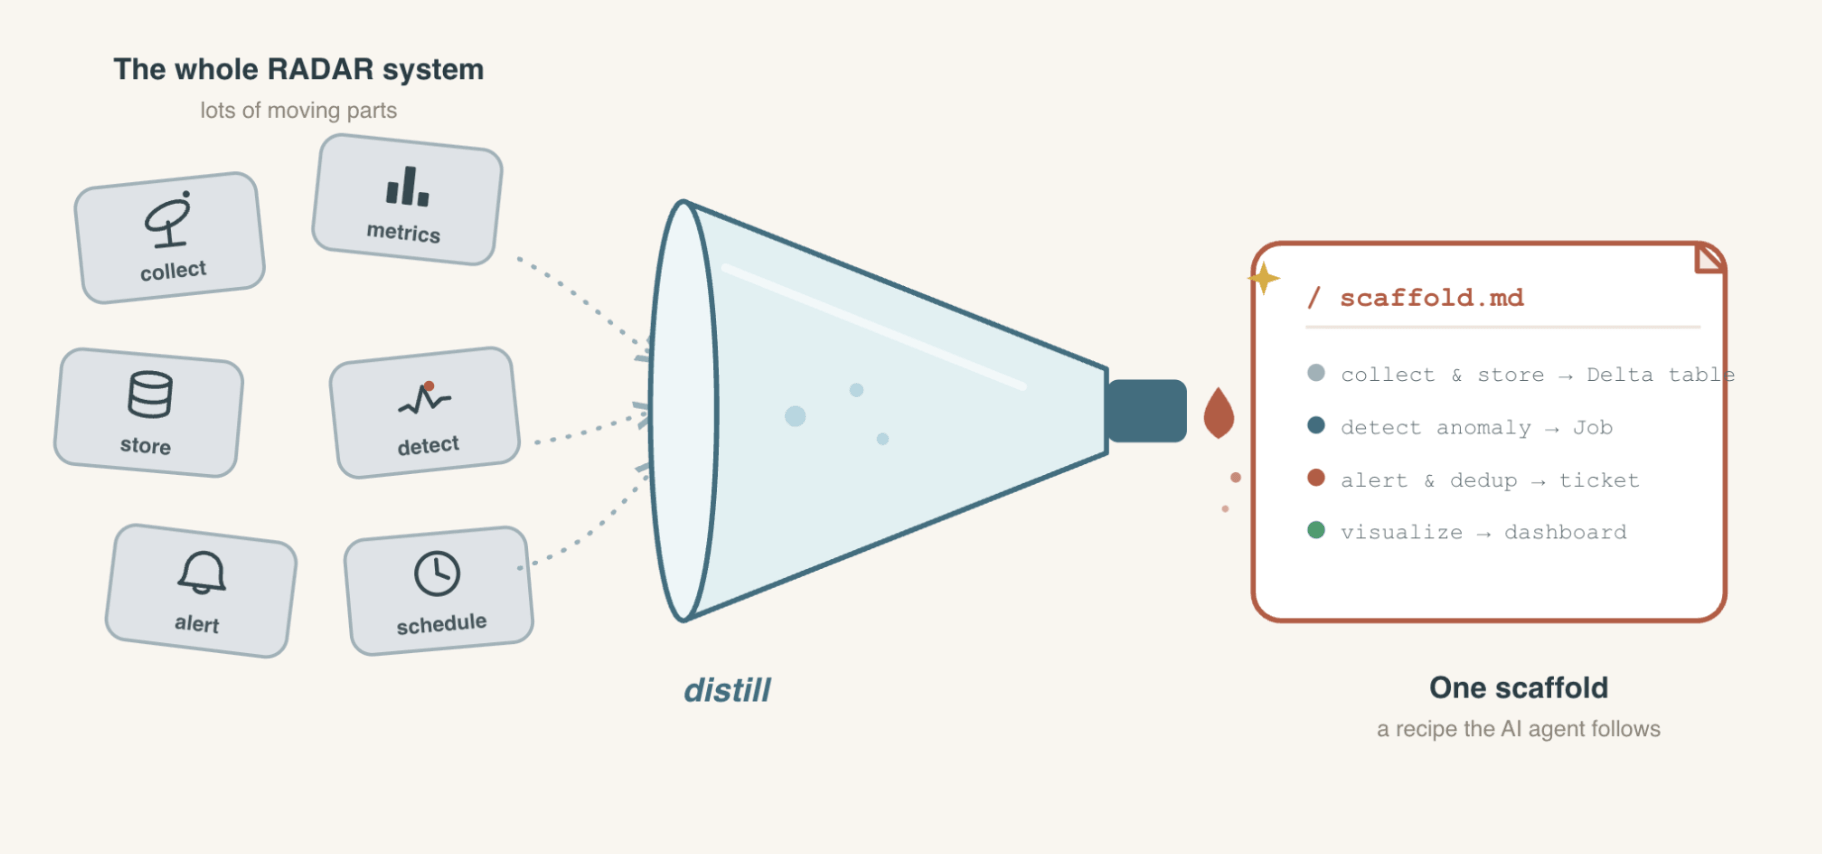
Then comes the payoff. You bring your own metric — wherever your signal lives — and hand the metric, the scaffold, and a short prompt to an AI agent. It builds the whole RADAR system for you, live on Databricks. You can follow the Github instructions on how to build one from a single prompt.
Takeaways
Two things to walk away with:
- Catch gray failures before they escalate. Green dashboards aren’t proof that customers are okay. Add real-time anomaly detection so a partial, silent failure surfaces in minutes, not days.
- Build RADAR on Databricks for whatever metric matters to you. The scaffold, the demo, and the prompt are all public — start from them.
Get the RADAR scaffold on GitHub
Because the best outcome isn’t a faster response to angry customers — it’s that your customers never have to discover your incidents for you.
Get the latest posts in your inbox
Subscribe to our blog and get the latest posts delivered to your inbox.