What is a Data Lakehouse?
Modern architecture unifying data warehousing and data lake capabilities with ACID transactions, schema enforcement, and governance for analytics and AI
- A data lakehouse combines the openness and scalability of data lakes with the reliability and governance of data warehouses in a single platform.
- By keeping all data in one place and supporting both BI and advanced analytics, a lakehouse removes the need for separate systems and complex data copies.
- Databricks Lakehouse is an example of this architecture, unifying streaming, batch, machine learning and governance on top of low cost cloud storage.
A data lakehouse is a new, open data management architecture that combines the flexibility, cost-efficiency, and scale of data lakes with the data management and ACID transactions of data warehouses, enabling business intelligence (BI) and machine learning (ML) on all data.
Data Lakehouse: Simplicity, Flexibility, and Low Cost
Data lakehouses are enabled by a new, open system design: implementing similar data structures and data management features to those in a data warehouse, directly on the kind of low-cost storage used for data lakes. Merging them together into a single system means that data teams can move faster as they are able to use data without needing to access multiple systems. Data lakehouses also ensure that teams have the most complete and up-to-date data available for data science, machine learning, and business analytics projects. 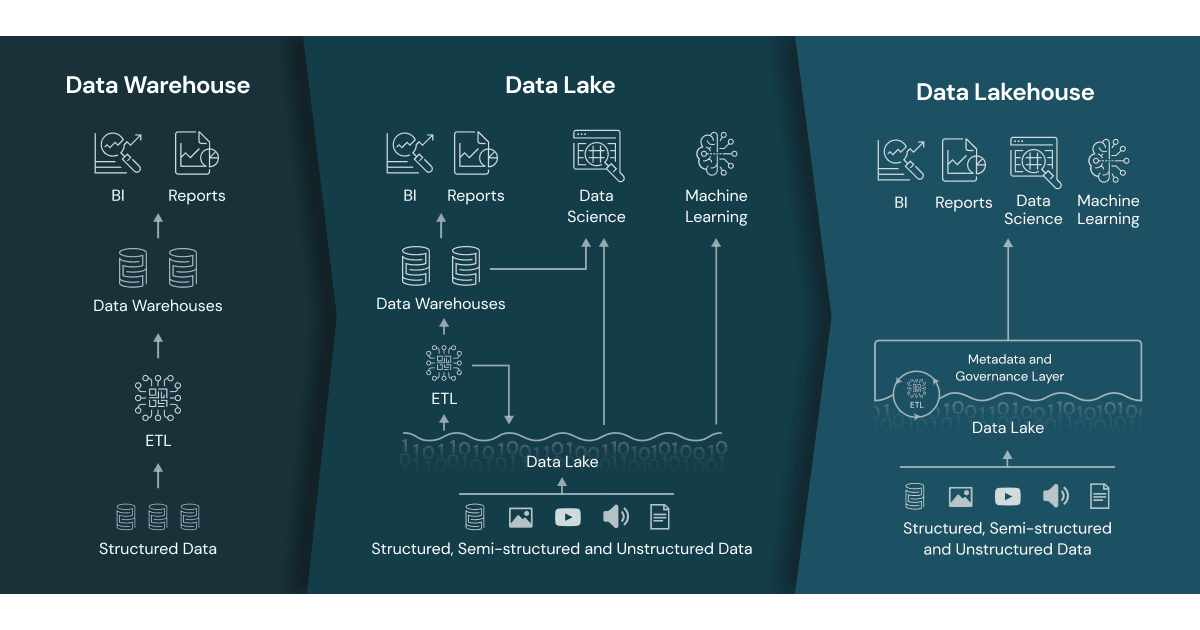
Key Technology Enabling the Data Lakehouse
There are a few key technology advancements that have enabled the data lakehouse:
- metadata layers for data lakes
- new query engine designs providing high-performance SQL execution on data lakes
- optimized access for data science and machine learning tools.
Metadata layers, like the open source Delta Lake, sit on top of open file formats (e.g. Parquet files) and track which files are part of different table versions to offer rich management features like ACID-compliant transactions. The metadata layers enable other features common in data lakehouses, like support for streaming I/O (eliminating the need for message buses like Kafka), time travel to old table versions, schema enforcement and evolution, as well as data validation. Performance is key for data lakehouses to become the predominant data architecture used by businesses today as it's one of the key reasons that data warehouses exist in the two-tier architecture. While data lakes using low-cost object stores have been slow to access in the past, new query engine designs enable high-performance SQL analysis. These optimizations include caching hot data in RAM/SSDs (possibly transcoded into more efficient formats), data layout optimizations to cluster co-accessed data, auxiliary data structures like statistics and indexes, and vectorized execution on modern CPUs. Combining these technologies together enables data lakehouses to achieve performance on large datasets that rivals popular data warehouses, based on TPC-DS benchmarks. The open data formats used by data lakehouses (like Parquet), make it very easy for data scientists and machine learning engineers to access the data in the lakehouse. They can use tools popular in the DS/ML ecosystem like pandas, TensorFlow, PyTorch and others that can already access sources like Parquet and ORC. Spark DataFrames even provide declarative interfaces for these open formats which enable further I/O optimization. The other features of a data lakehouse, like audit history and time travel, also help with improving reproducibility in machine learning. To learn more about the technology advances underpinning the move to the data lakehouse, see the CIDR paper Lakehouse: A New Generation of Open Platforms that Unify Data Warehousing and Advanced Analytics and another academic paper Delta Lake: High-Performance ACID Table Storage over Cloud Object Stores.
History of Data Architectures
Background on Data Warehouses
Data warehouses have a long history in decision support and business intelligence applications, though were not suited or were expensive for handling unstructured data, semi-structured data, and data with high variety, velocity, and volume.
Emergence of Data Lakes
Data lakes then emerged to handle raw data in a variety of formats on cheap storage for data science and machine learning, though lacked critical features from the world of data warehouses: they do not support transactions, they do not enforce data quality, and their lack of consistency/isolation makes it almost impossible to mix appends and reads, and batch and streaming jobs.
Common Two-Tier Data Architecture
Data teams consequently stitch these systems together to enable BI and ML across the data in both these systems, resulting in duplicate data, extra infrastructure cost, security challenges, and significant operational costs. In a two-tier data architecture, data is ETLd from the operational databases into a data lake. This lake stores the data from the entire enterprise in low-cost object storage and is stored in a format compatible with common machine learning tools but is often not organized and maintained well. Next, a small segment of the critical business data is ETLd once again to be loaded into the data warehouse for business intelligence and data analytics. Due to multiple ETL steps, this two-tier architecture requires regular maintenance and often results in data staleness, a significant concern of data analysts and data scientists alike according to recent surveys from Kaggle and Fivetran. Learn more about the common issues with the two-tier architecture.
The agentic AI playbook for the enterprise

Additional Resources
- What is a Lakehouse? - Blog
- Lakehouse Architecture: From Vision to Reality
- Introduction to Lakehouse and SQL Analytics
- Lakehouse: A New Generation of Open Platforms that Unify Data Warehousing and Advanced Analytics
- Delta Lake: The Foundation of Your Lakehouse
- The Databricks Lakehouse Platform
- Data Brew Vidcast: Season 1 on Data Lakehouses
- The Rise of the Lakehouse Paradigm
- The Data Lakehouse Platform for Dummies
Frequently Asked Questions (FAQ)
What is a data lakehouse?
A data lakehouse combines the flexible, low-cost storage of a data lake with the reliability, governance, and query performance of a data warehouse on one platform that supports both BI and machine learning.
What is Delta Lake and why is it important?
Delta Lake is an open source storage layer adding ACID transactions, schema enforcement, time travel, and scalable metadata to data lake storage. It is the default table format in Databricks and the foundation of the lakehouse. Delta Lake is the open source storage layer that makes the lakehouse technically possible by adding ACID transactions, schema enforcement, and time travel to cloud object storage. This explains how Delta Lake became the default table format in Databricks and why it is foundational to the lakehouse architecture described in this post.
What is a data lake and what are its limitations?
A data lake is a low-cost storage system for raw data in any format. Without governance and ACID support, data lakes suffer from poor data quality, inconsistent access controls, and reliability issues, collectively known as the data swamp problem. The data swamp problem means that poor data quality and inconsistent governance in unmanaged data lakes are key motivations for the lakehouse design. This explains how the lakehouse retains the low-cost, flexible storage of a data lake while adding the reliability and governance features that data lakes lack.
What is a data warehouse and how does it compare to a lakehouse?
A data warehouse is a structured, SQL-optimized system for business intelligence. Unlike a lakehouse, traditional warehouses use proprietary formats, struggle with unstructured data, and require costly ETL pipelines from raw storage. Traditional data warehouses use proprietary closed formats and separate ETL pipelines from raw storage, against the lakehouse approach of open formats stored in a single location. Lakehouse eliminates the duplication of data and cost of maintaining two separate systems.
What is time travel in Delta Lake?
Time travel lets you query historical versions of a Delta table using a timestamp or version number, enabling auditing, debugging, and rollback without separate backup systems. Time travel is one of the concrete advantages the lakehouse delivers over a traditional data lake, allowing teams to query historical versions of data without separate backup infrastructure. This capability is built directly into Delta Lake and is available on every Databricks table.
Frequently Asked Questions
What's the difference between a data lake and a lakehouse?
A data lake stores raw data in a variety of formats but lacks transaction support, data quality enforcement, and consistency, which makes it difficult to mix appends and reads or combine batch and streaming jobs. A lakehouse closes these gaps by adding warehouse-like features—such as ACID transactions, schema enforcement, and governance—directly on top of low-cost cloud object storage, while keeping the openness and scale of a data lake. This lets teams run BI, data science, and machine learning workloads against a single copy of data instead of maintaining separate lake and warehouse copies.
Why can't a traditional data warehouse handle today's data needs?
Traditional data warehouses were built for structured data, so they aren't well suited to the unstructured, semi-structured, and high-volume, high-velocity data many enterprises now generate. This limitation pushes companies toward running additional specialized systems—such as streaming, time-series, graph, or image databases—alongside the warehouse, adding complexity and delay as data has to be copied between systems. A lakehouse addresses this by supporting the full range of data types within a single platform.
What open source formats can be used to build a lakehouse?
Companies building their own lakehouse can use open source file formats such as Delta Lake, Apache Iceberg, or Apache Hudi. These formats bring warehouse-style data management, including ACID transactions and schema enforcement, onto data stored in open, standardized formats such as Parquet. Because the formats are open, a variety of engines and tools can access the underlying data directly rather than going through a proprietary interface.
Why does decoupling storage from compute matter in a lakehouse?
Decoupling storage from compute lets a lakehouse scale each independently using separate clusters, allowing the system to support many more concurrent users and larger data sizes than architectures where the two are tied together. This separation also helps manage cost, since compute resources can be scaled up or down without moving or duplicating the underlying data. Some modern data warehouses share this property, but it's a defining feature of lakehouse design.
What is Delta Lake and how does it relate to the lakehouse?
Delta Lake is an open source, open format data management and governance layer that combines features of data lakes and data warehouses, including ACID transactions, scalable metadata handling, and schema enforcement. It is compatible with Apache Spark APIs, so it can be used in existing Spark applications without code changes. Within a lakehouse architecture, Delta Lake is one of the open table formats used to bring warehouse-style reliability directly to data stored in a data lake.
Get the latest posts in your inbox
Subscribe to our blog and get the latest posts delivered to your inbox.